aws.amazon.com
·
Sep 15
Optimizing cost and latency with Amazon Bedrock prompt caching
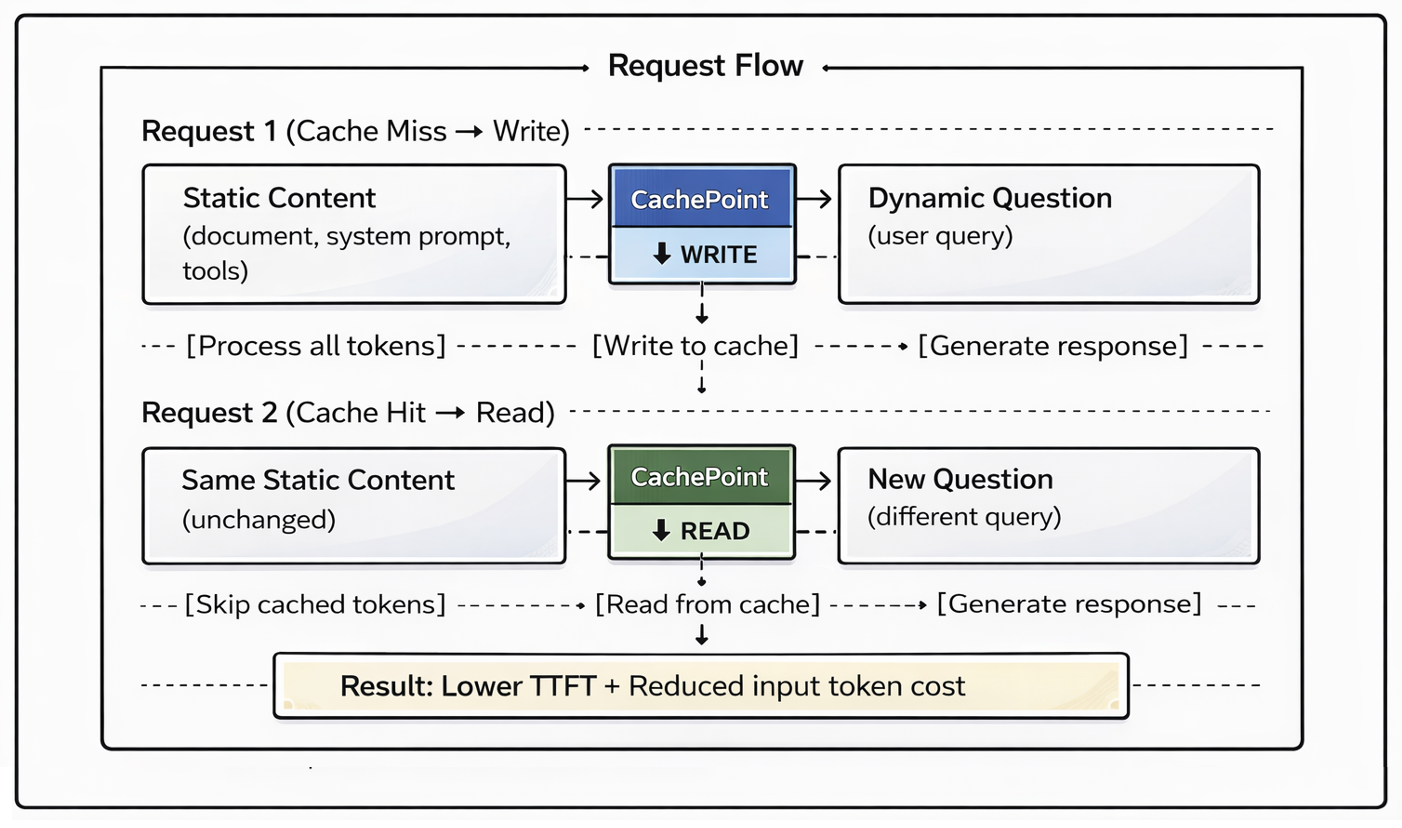
Prompt caching in Amazon Bedrock can cut input token costs by up to 90% when you repeatedly send the same context to foundation models. This post walks through six practical prompt caching scenarios using the Converse API: message content, system prompt, tool definition, mixed TTL, tenant isolation, and LangChain integration.