aws.amazon.com
·
5d
Stop guessing auto scaling targets for TTS on Amazon SageMaker AI
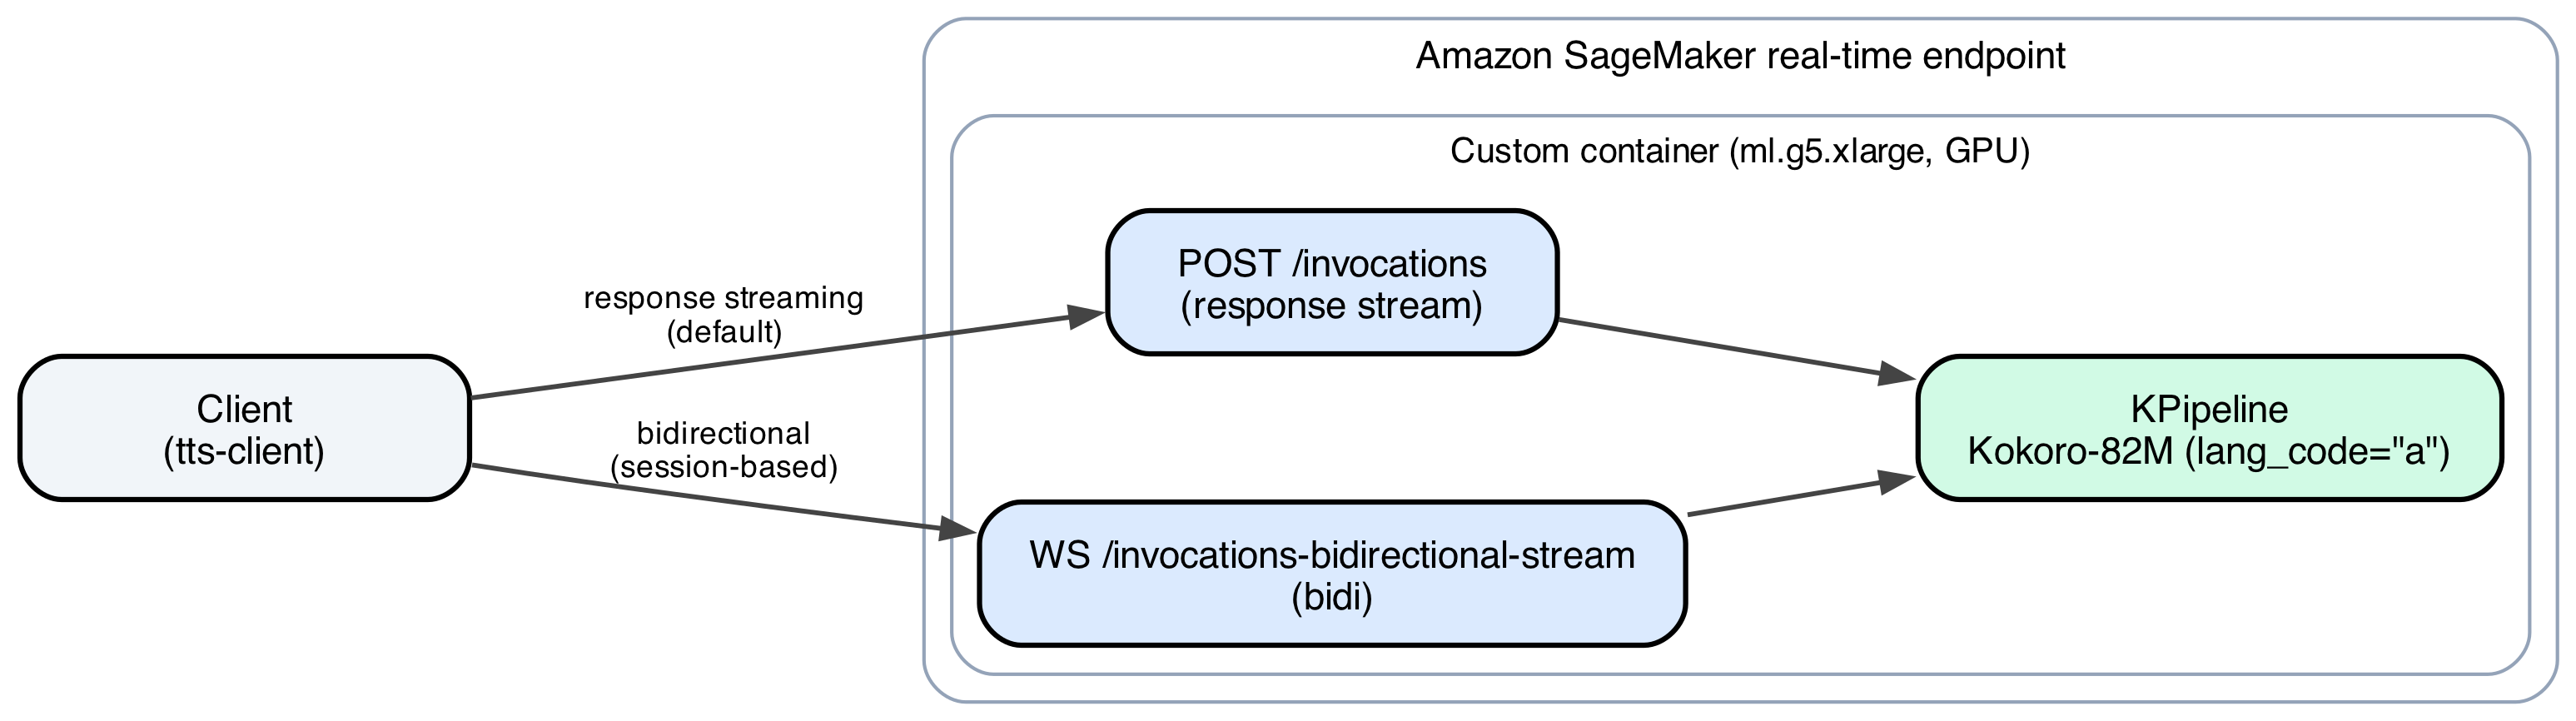
Teams deploying custom text-to-speech models on Amazon SageMaker AI often guess at autoscaling thresholds, and a wrong guess either wastes GPU spend or breaches a latency SLO. This post deploys Kokoro-82M as a custom container and derives a measured autoscaling policy from two live-endpoint measurements, Q_max and T_total, instead of guesswork.