aws.amazon.com
·
6d
Fine-tuning GPT-OSS-20B for multilingual reasoning on Amazon SageMaker HyperPod
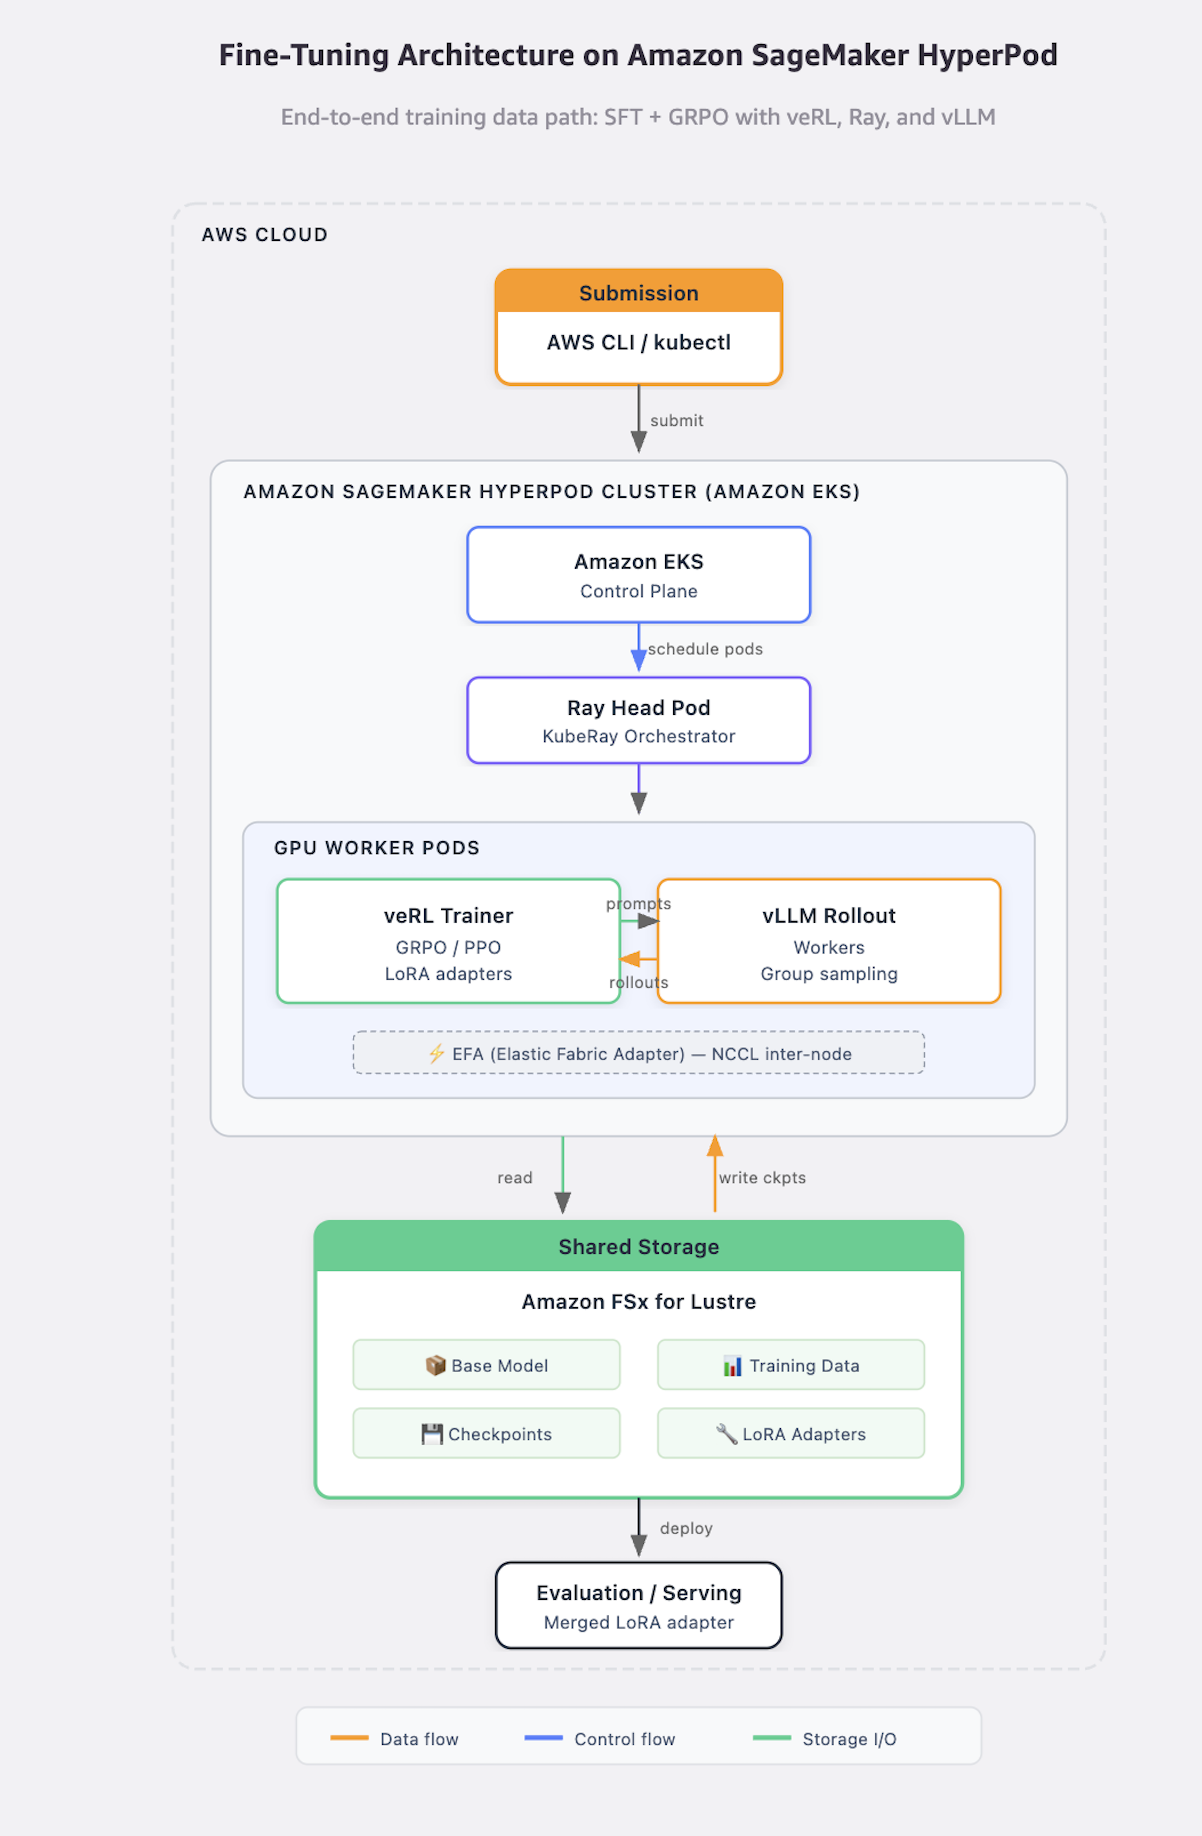
Learn how we fine-tuned GPT-OSS-20B for multilingual reasoning on Amazon SageMaker HyperPod, and how to decide between supervised fine-tuning (SFT) and reinforcement learning with GRPO. SFT took reasoning-language accuracy from 22% to 100%, and GRPO added measurable gains where headroom existed.