aws.amazon.com
·
Oct 19
Push-based KV transfer to improve TTFT and TPOT for disaggregated inference in vLLM
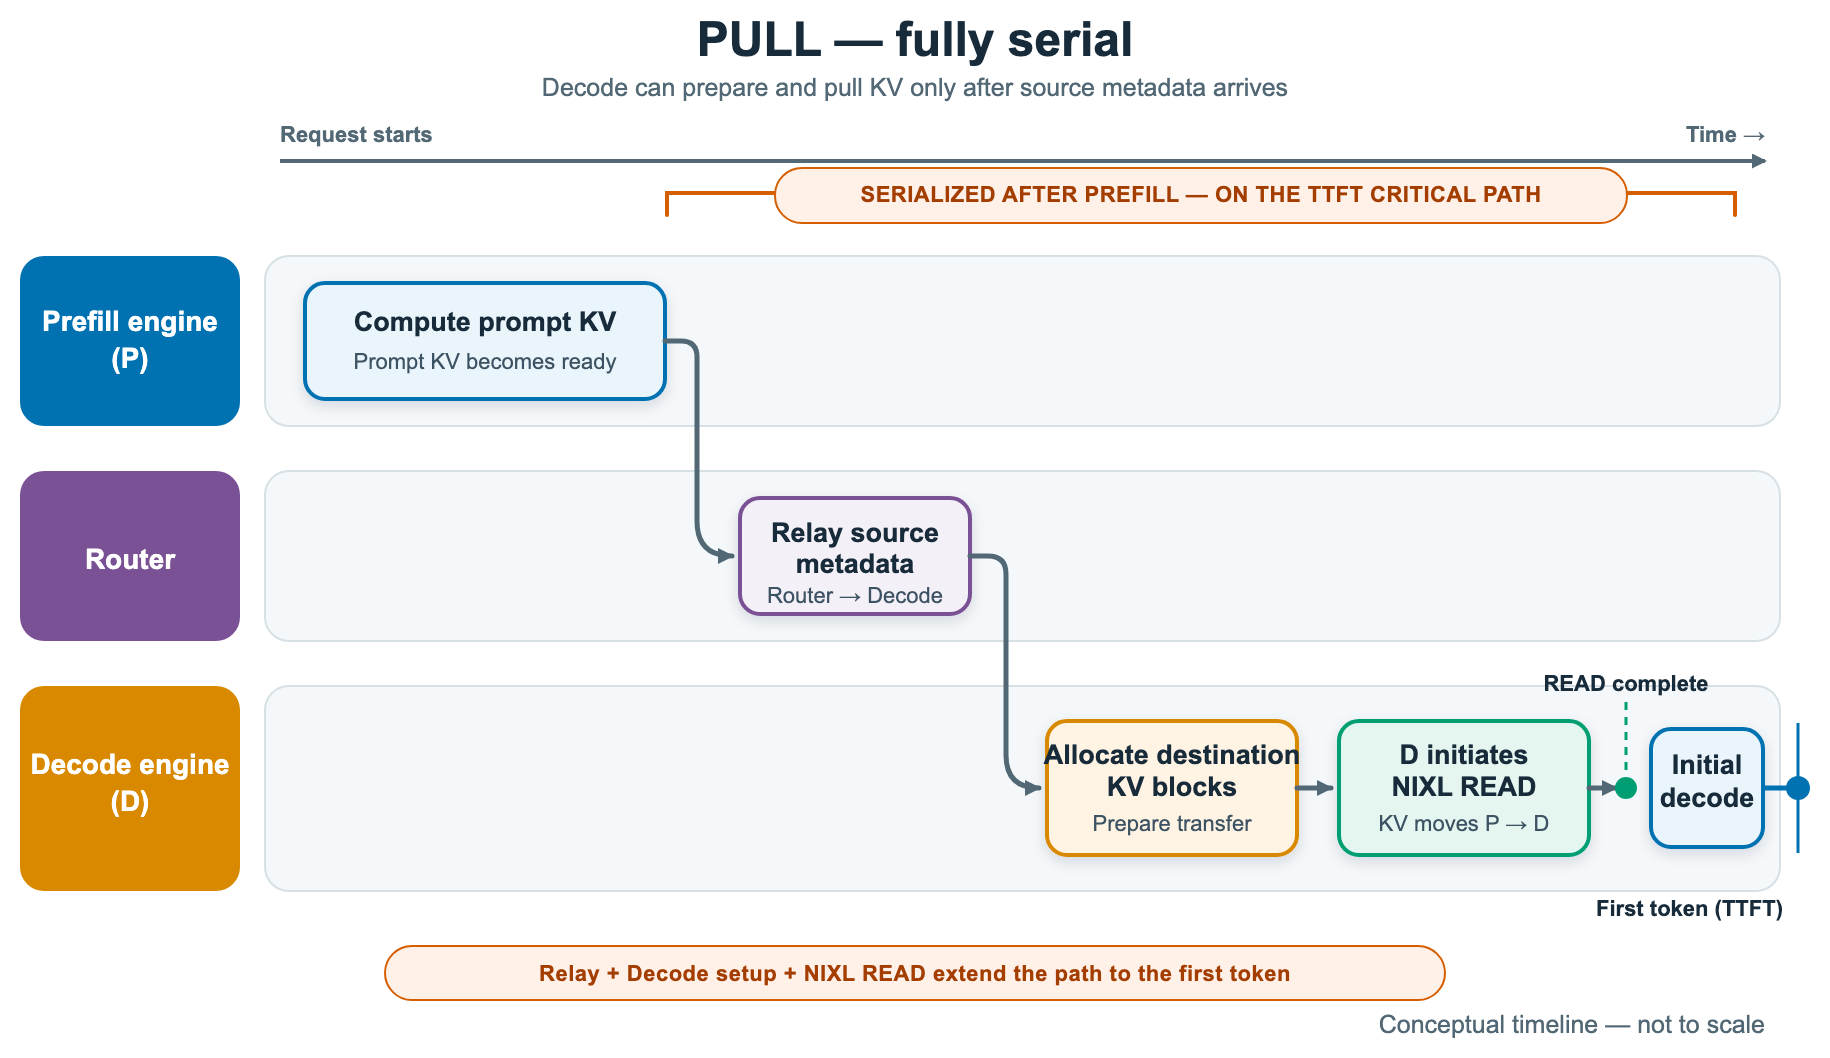
vLLM's prefill-decode disaggregation splits LLM inference across engine instances but must transfer the KV cache between them. This post introduces a push-based NIXL connector that moves transfer coordination off the critical path, delivering up to 3x better TTFT and 30% better TPOT in benchmarks on Amazon EC2 P5en instances with AWS EFA.