www.marktechpost.com
·
Sep 29
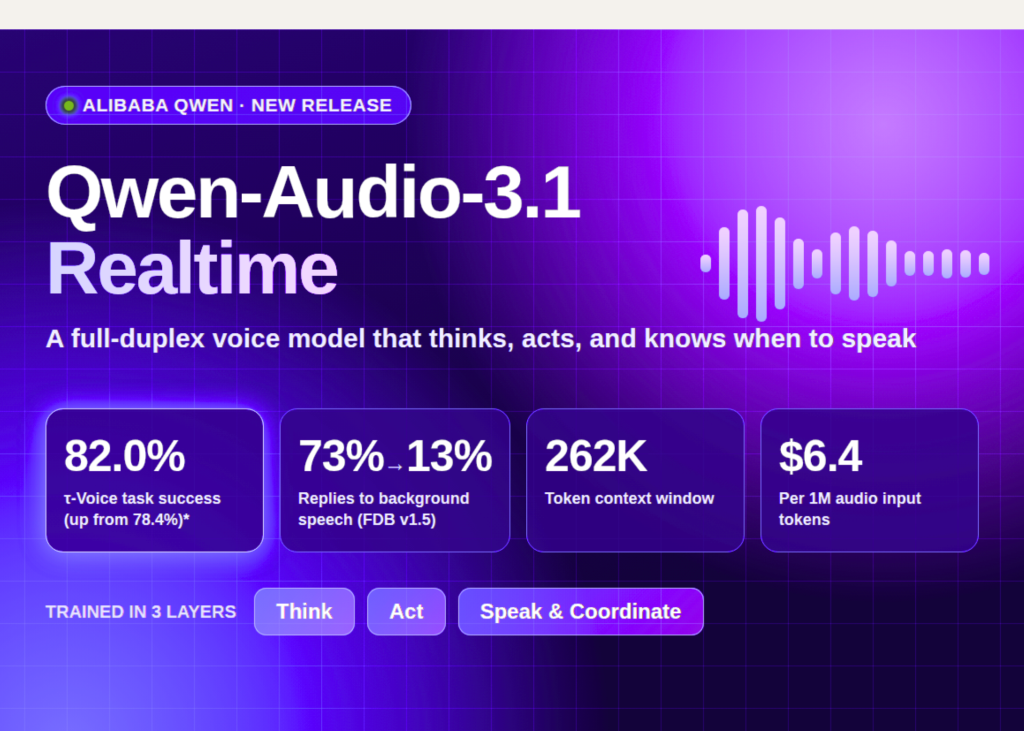
Alibaba Qwen Releases Qwen-Audio-3.1-Realtime: A Full-Duplex Voice Model Trained to Think, Act, and Decide When to Speak
Alibaba's Qwen team released Qwen-Audio-3.1-Realtime, a full-duplex voice model trained to reason, call tools and decide when to speak. On a τ-Voice adaptation, task success rises to 82.0% from 78.4%. Replies to background speech drop from 73% to 13%. It is available now as an API on QwenCloud. The post Alibaba Qwen Releases Qwen-Audio-3.1-Realtime: A Full-Duplex Voice Model Trained to Think, Act, and Decide When to Speak appeared first on MarkTechPost.