www.marktechpost.com
·
Sep 24
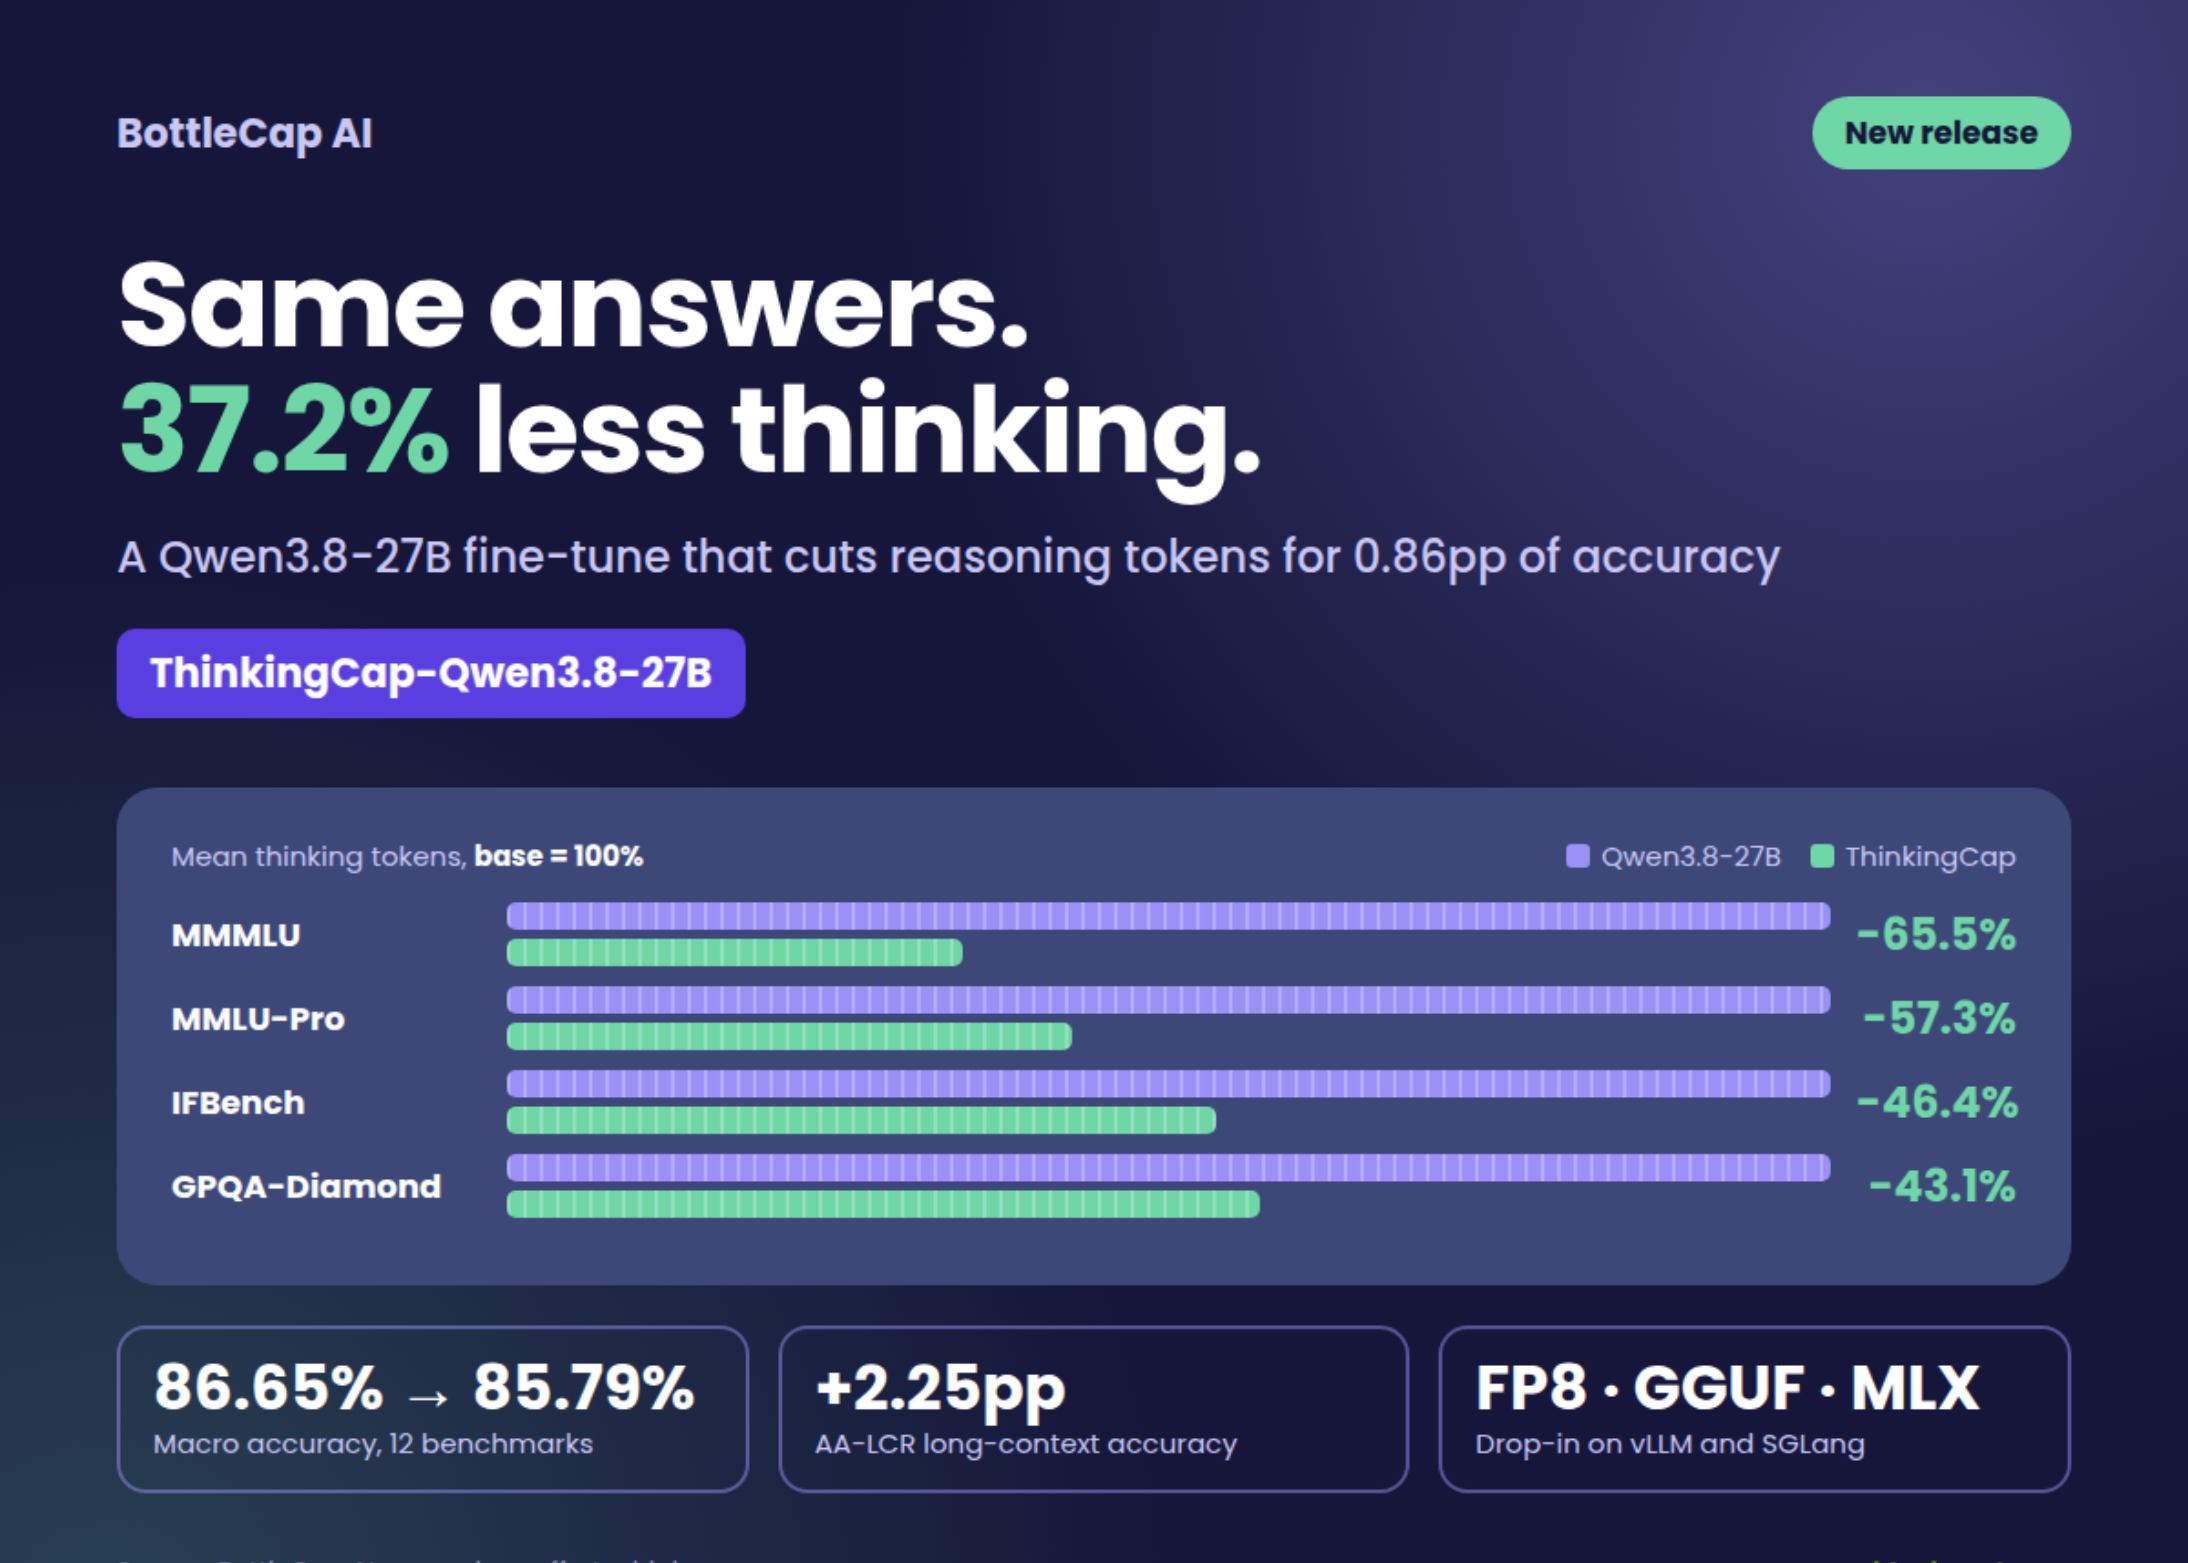
BottleCap AI Releases ThinkingCap-Qwen3.8-27B: 37.2% Fewer Thinking Tokens at a 0.86pp Accuracy Cost
BottleCap AI has released ThinkingCap-Qwen3.8-27B, a fine-tune of Qwen3.8-27B that spends 37.2% fewer thinking tokens across 12 benchmarks. Macro accuracy moves from 86.65% to 85.79%, and long-context AA-LCR improves by 2.25pp. The model is a drop-in replacement on vLLM and SGLang, with FP8, NVFP4, GGUF and MLX builds. The post BottleCap AI Releases ThinkingCap-Qwen3.8-27B: 37.2% Fewer Thinking Tokens at a 0.86pp Accuracy Cost appeared first on MarkTechPost.